Saturday, February 03, 2007

The control with ID 'UpdatePanel1' requires a ScriptManager on the page. The ScriptManager must appear before any controls that need it

When I first migrate the DataView form the original place to UpdatePanel, recompile it and error message returned:

"The control with ID 'UpdatePanel1' requires a ScriptManager on the page. The ScriptManager must appear before any controls that need it"


Solution:

http://forums.asp.net/thread/1527394.aspx


You need to add the ScriptManager to your page. The ScriptManager control manages script resources for Microsoft ASP.NET AJAX pages


id="form1" runat="server" /> ID="ScriptManager1" runat="server" / />


powered by performancing firefox

Wednesday, January 31, 2007

Meeting with supervisor

After meeting with supervisor, Dr Yuen, Geoffrey and Wah shows their view points on my project system.

Firstly, Wah ask what if the URL share among the users are identical. For example, if User A save hk.yahoo.com as a Portal site and User B save hk.yahoo.com as a search engine, the URL will be duplicated in the database. Well, this is not a problem becuase, say in the YouTube system, when we search "Frilled Shark", more than 4 same vedio chips will be returned and, it indicated that the searching result is accurate. Dr Yuen suggested that one of the development approach in my stage is that, I can enhance the accuracy on the searching data among the various items in the system.

Afterward, Dr Yuen asked the selling point of my project, well I can hardly tell the different, I response by saying "Well, by comparing the one man work, I do better than them as a team :p" Seriously, the furture mile stoneof my project probably support the different character, espeacially the Asian fonts because, for example, the FURL.net have problem on saving the Traditional Chinese character, I think I will/need to trigger this problem.

Dr Yuen also suggested me to integrate the two algorithms into one and implementation this 'new' algorithm on doing associate analysis. These two algorithm, Apriori Algorithm and FP-Tree, have different approach.
Apriori Algorithm is base on counting the itemsets' frequency. If the frequent of itemset is low, elimnate that item(s) and the remaining enter the next stage. Finally, the resulting item(s) is/are the most likely be related among the other tags.
FP-Tree,on the other hand, is based on classifying the frequency of the tags used into the hush table. The most frequent tags will get the higher position in the hush table and lower frequent items list under them. Under this method, the completeness of the association pattern maintains, and the computational power required is lower than Apriori method.

Lastly, Dr Yuen suggested that the system should utliminately make LESS involvement, like 1. totally no input of tags by user and 2. eliminate the unneccessary user interaction on the site but the newly added data can embed to the system automatically. I think the first one can be achieved by combining the AJAX and Association Pattern suggestion like the one did by Del.icio.us. I think this function will be implement in Phase 3

Progress log in Janurary

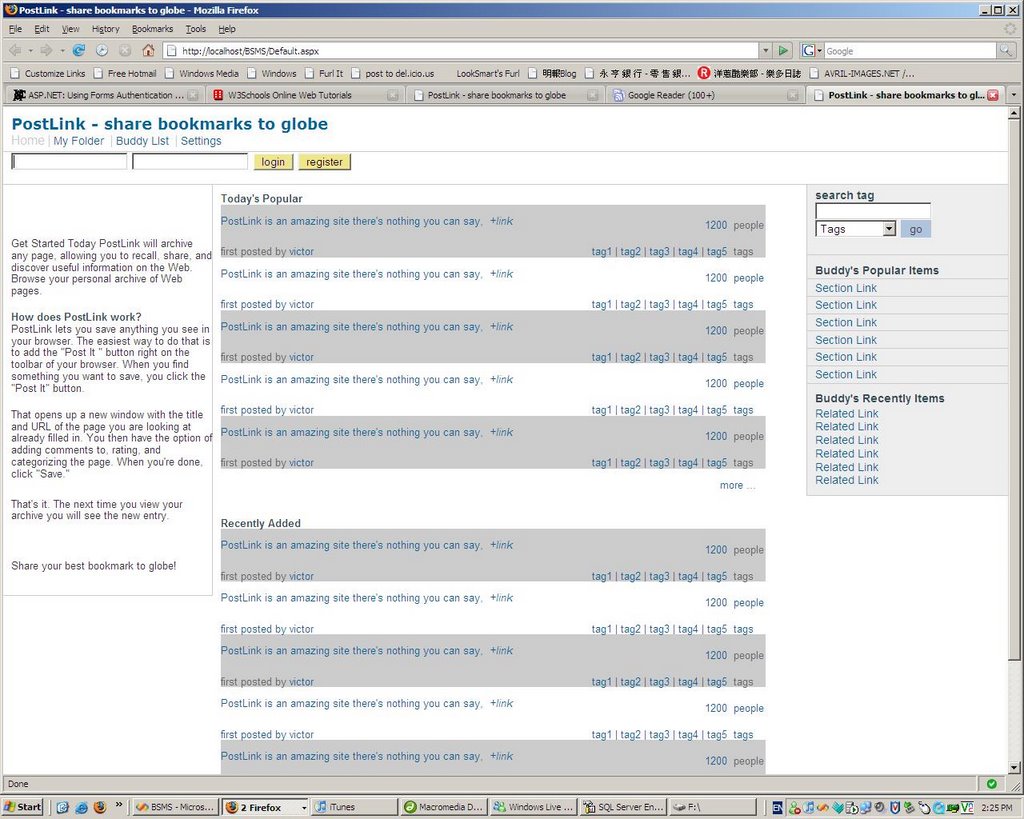
The project has entered the major mile stone and the link suggestion and searching engine using in the site are building. In Jan., beside finish writing the User Interface of the site like user registration, buddy list update, adding the new link and adding new link throw the Bookmarklet have been finished.
In Feb., I will focus on developing the Association Analysis which is used for frequent pattern mining. After finishing this functional implementation, the project will be almost done and enter the testing phases.

The Alpha version of my project can be accessed through this link:
http://144.214.121.62/BSMS/Default.aspx

The latest changes and update of my progress can be checked via the follow link:
http://cslabvictor.blogspot.com/

Saturday, January 27, 2007

Bookmarket tool

http://www.bookmarklets.com/tools/categor.html

Work on the bookmark system like remove the JavaScript in the viewing pages, send the searching value into the search engine etc.


powered by performancing firefox

Friday, January 26, 2007

ASP.NETWeb: The Official Microsoft ASP.NET 2.0 Site: Videox

http://www.asp.net/learn/videos/default.aspx?tabid=63#ajax

Videos for ASP.NET 2.0 beginner and AJAX developer


http://blogs.msdn.com/mattgi/archive/2007/01/23/asp-net-ajax-validators.aspx

Known issue after installing the AJAX v1.0 extension for ASP.NET 2.0

ASP.NET AJAX Validators

ASP.NET
AJAX provides new APIs for registering script with the ScriptManager.
Using these APIs allows controls to work well with partial rendering.
Without them, controls placed inside an UpdatePanel won't work as
expected. In previous CTP releases of ASP.NET AJAX, we had a set of
validator controls that derived from the v2.0 controls and used the new
APIs. This made them work well with ASP.NET AJAX. WindowsUpdate will
soon include a version of System.Web that can take advantage of the new
APIs. So the new controls which would have been redundant have been
removed. However, the update isn't available yet and ASP.NET AJAX has
been released. So, in the short-term, the source code for a set of
custom validator controls that work with partial rendering is available
here.


powered by performancing firefox

Sunday, January 21, 2007

Web mining for web personalization

Web mining for web personalization
Magdlini Eirinaki and Michalis Vazirgiannis
Athens University of Economics and Business

ACM Transaction on Internet Technology, Vol. 3., No 1, Feb., 2003, Page 1 - 27

Introduction

Web personalization is defined as any action that adapts the information or services provided by a Web site to the needs of a particular user or a set of users, taking advantage of the knowledge gained from the user’s navigational behavior and individual interests, in combination with the content and the structure of the web site.

Objective:

The objective of a web personalization system is to provide users with the information they want or need, without expecting from them to ask for it explicitly.

The content management is the process classifying the content of a web site in semantic categories in order to make information retrieval and presentation easier for the users. Content management is very important for web sites whose content is increasing on a daily basis, such as news sites or portals.

Web personalization

… the analysis of the collected data, and the determination of the actions that should be performed. The ways that are employed in order to analyze the collected data include content-based filtering, collaborative filtering, rule-based filtering and Web usage mining.

Content-based filtering systems: are solely based on individual users’ preferences. The system tracks each user’s behavior and recommends items to them that are similar to items the user liked in the past.

Collaborative filtering systems invite users to rate objects or divulge their preferences and interests to them. This is based on the assumption that users with similar behavior have analogous interests.

The data mining methods that are employed are: association rule mining, sequential pattern discovery, clustering and classification. This knowledge is then used from the system in order to personalize the site according to each user’s behavior and profile.

User profiling

In order to personalize a web site the system should be able to distinguish between different users or groups of users. This process is called user profiling and its objective is the creation of an information base that contain the preferences, characteristics, and activities of the users.

Log analysis and web usage mining:

By applying statistical and data mining methods to the web log data, interesting patterns concerning the user’s navigational behavior can be identified, such as users and page clustering, as well as possible correlations between web pages and user groups.

The web usage mining process can be regards as a three-phase process, consisting of the data presentation, pattern discovery, and pattern analysis phases. In the first phase, log data are preprocessed in order to identify users’ session, page views and so on. In the second phases, statistical methods, as well as data mining methods (such as association rules, sequential pattern discovery, clustering and classification are applied in order to detect interesting patterns.

Most important of all is the user identification issue. More accurate approaches for a priori identification of unique visitors are the use of cookies or similar mechanisms of the requirement for be the reluctance of users to share personal information.

Web usage mining

More advanced data mining methods and algorithms tailored appropriately are use in the Web domain include association rules, sequential pattern discovery, clustering and classification. Association rule mining is used in order to reveal correlations between pages accessed together during a server session. It can reveal association between groups of users with specific interests.

Sequential pattern discovery is an extension of association rules mining in that it reveals pattern of concurrence incorporating the notion of time sequence. Clustering is used to group together items that have similar characteristics. In the context of web mining, we can distinguish two cases, user clusters and page clusters.

Page clustering identifies group of pages that seem to be conceptually related according to the user’s perception. User clustering results in group of users that seems to behave similarly when navigating through a Web site.

Classification is a process that maps a data item into one of several predetermined classes. In web domain classes usually represent different user profiles and classification is performed using selected features that describe each user’s category. The most common classification algorithm are decision trees, Naïve Bayesian classifier, neural networks, and so on.

After discovering patterns from usage data, a further analysis has to be conducted. The exact methodology that should be followed depends on the technique previously used. The most common ways of analyzing such patterns are either by using a query mechanism on a database where the results are stored, or by loading the results into a data cube and then performing OLAP operations. Additionally, visualization technique are used fir an easier interpretation of formation convening the web site there can be extracted useful knowledge for modifying the site according to the correlation between user and content groups.

Research initiatives

Most of the efforts focus on extracting useful patterns and rules using data mining techniques in order to understand the users’ navigational behavior, so that decision concerning site restructuring or modification can then be made by humans. In several cases, a recommendation engine helps the user navigates through a site.

A different approaches is adopted by Zaiane et al. the authors combine the OLAP and data mining techniques and a multidimensional data cube, to extract interactively implicit knowledge. Their webLogMiner system after filtering the data contained in the web log, transforms them into a relational database. In the next phase a data cube is built, each dimension representing a field with all possible values described by attributes. OLAP technology s then used in combination with data mining techniques for prediction, classification and time-series analysis of web log data.

Pattern discovery is accomplished through the use of general statistics algorithms and data mining techniques such as association rules, sequential pattern analysis, clustering and classification. the result then analyzed through a simple knowledge query mechanism, a visualization tool, or the information filter, that makes use of the preprocessed content, and structure information to automatically filter the results of the knowledge discovery algorithms.

Saturday, January 13, 2007

Function that like StringTokenizer in C#

Function that like StringTokenizer in C#

Question: 我有一个字符串,我想以空格把里面的单词分开,以前在Java中有StringTokenizer很方便,不知C#中有没有类似的.

using System;

using System.Text.RegularExpressions;


class SplitTest

{

public static void Main()

{

String s = "Hello, Houston,I,am,coming";

Console.WriteLine("First example:");

Console.WriteLine("Original stirng:" + s);

Console.WriteLine("After splitting:");


String[] tokens = Regex.Split(s,",");

for (int i=0; i tokens.Length; i++)

Console.WriteLine(tokens[i]);


s = "Hello | Houston | I | am | coming";


Console.WriteLine("Second example:");

Console.WriteLine("Original stirng:" + s);

Console.WriteLine("After splitting:");


tokens = Regex.Split(s,@"\s*\|\s*");

for (int i=0; i tokens.Length; i++)

Console.WriteLine(tokens[i]);

}


}


powered by performancing firefox

Thursday, January 11, 2007

get RETURN VALUE from SYBASE stored procedure [Also apply to MSSQL2000]

http://forums.asp.net/thread/1333707.aspx

I can handle the returned value base on the storedProcedure conduct in MSSQL2000 with the following code:
ASP.NET
try
{
storedProcCommand.CommandType = CommandType.StoredProcedure;
storedProcCommand.Parameters.Add("@userid", Session["UserName"].ToString());
storedProcCommand.Parameters.Add("@buddyid", tbNewBuddy.Text);
cn.Open();

if (Convert.ToString(storedProcCommand.ExecuteScalar()) == "Success")
{
lbDisplay.Text = "New buddy added. / />
}
else
{
lbDisplay.Text = "Sorry, there is no such buddy. / />
}
}// end try
catch (Exception ex)
{
lbDisplay.Text = ex.ToString() + @" / />
}
finally
{
cn.Close();
}

Stored Procedure in SQL2000
CREATE PROCEDURE userBuddyAdd
@userid nvarchar(50),
@buddyid nvarchar(50)

With Recompile
AS
Declare
@intCheckBuddyExist int,
@intCheckAdd int,
@intSameUserId int
-- Check if buddy exist in the userinfo
Select @intCheckBuddyExist = count(*) from userinfo where userid = @buddyid

-- Check if the buddy id is user id
Select @intSameUserId = count(*) from userbuddy where userid = @userid and userid = @buddyid

-- Check if buddy already added
Select @intCheckAdd = count(*) from userbuddy where userid = @userid and buddyid = @buddyid

-- Add Buddy only if not been added
if @intCheckBuddyExist = 1 and @intCheckAdd = 0 and @intSameUserId = 0
begin
INSERT INTO userbuddy VALUES(@userid,@buddyid)
if @@Error = 0 Goto SUCCESS
end

-- Return addition fail if the buddy does not exist in the list
if @intCheckBuddyExist = 0
Goto PROBLEM
Return 0

PROBLEM:
Select 'Fail'
Return 1

SUCCESS:
Select 'Success'
Return 2

GO

Monday, January 08, 2007

http://support.microsoft.com/default.aspx/kb/925336

Error message when you try to install a large Windows Installer package or a large Windows Installer patch package in Windows Server 2003 or in Windows XP: "Error 1718. File was rejected by digital signature policy"

View products that this article applies to.
Article ID : 925336
Last Review : October 3, 2006
Revision : 1.1
SYMPTOMS
When you try to install a large Microsoft Windows Installer (.msi) package or a large Microsoft Windows Installer patch (.msp) package on a computer that is running Microsoft Windows Server 2003 or Microsoft Windows XP, you receive the following error message:
Error 1718. File FileName was rejected by digital signature policy.
Back to the top Back to the top
CAUSE
This problem occurs when the computer has insufficient contiguous memory for Windows Server 2003 or Windows XP to verify that the .msi package or the .msp package is correctly signed.
Back to the top Back to the top
WORKAROUND
To work around this problem, follow these steps:
1. Click Start, click Run, type control admintools, and then click OK.
2. Double-click Local Security Policy.
3. Click Software Restriction Policies.

Note If no software restrictions are listed, right-click Software Restriction Policies, and then click Create New Policy.
4. Under Object Type, double-click Enforcement.
5. Click All users except local administrators, and then click OK.
6. Restart the computer.
Important After you follow the previous steps, local administrators can install the .msi package or the .msp package. After the package is installed, reset the enforcement level by following the previous steps. In step 5, click All users instead of All users except local administrators.

Seessment result on Interim report

You got B grade for your interim report. Here is the comment from your supervisor:


------------------------------


The
related work section is good and the report is well-organized.
there are some minor mistakes on the formatting and the
writting, the student has done a reasonbly good work


powered by performancing firefox

Friday, January 05, 2007

Finished building of user registeration, add new item and modify user settings


In the past 10 days, the user registeration has been finished and tested. On the other hand, user can add other buddy that has been registered. User now can add itme under their account and they can add other buddy by inputting their userid. Once buddy inserted a new item, user can view that itme under the buddy's latest update page.

User now can change their setting like setting the default topic as the last-used, search the information based on the tags, or keyword or use both of them.

The next major implementation will be building the searching function which I think is the most difficult part of the project. I wish I can finish the basic function, namely phase one of the searching function like return the related item base on the tag that user input in the search field first. After then, it will be improved by adding function like searching the alike information based on user's preferences and user's tags trendency, better result should be return in phase two.
In my progress, I expect phase one can be finished by 15th January, 2007

Friday, December 22, 2006

Login and Logout finished


Login and Logout functions finished.
I am working on the registeration and the item inserting; both working by the stored-procedures in the SQL server. Expected Finished date: 25th December, 2006 Mid-night.

Thursday, December 21, 2006

ASP.NET: Using Forms Authentication in ASP.NET

ASP.NET: Using Forms Authentication in ASP.NET

References:

User Interface is finished

The User Interface has been update and finished.
Since this is the migration of functions from the old UI to this new UI, I am conducting the implementing of the basic functions like login, logut, insert new itmes like URL, tags, topic selection and comments etc. I planned the implmentation will be finished within 5 day.

Saturday, December 16, 2006

Resume the development work

I have already restarted my work from 16th Dec., 2006. 1 day after my final examination this semester.

Thursday, November 30, 2006

Web 2.0 from Dr Andy Chun

Web 2.0 from Dr Andy Chun
http://www.zdnetasia.com/blog/web2/

Saturday, November 11, 2006

Suggestion on making tag on classification

Although there are no standard guidelines on good tag selection practices, those in the folksonomy community have offered many ideas. Some “best practices” including:

  1. using plurals rather than singulars
  2. using lower case.
  3. grouping words using an underscore,
  4. following tag convention started by others and
  5. adding synonyms.

Many folksonomies allow users to modify this tags, and there is considerable scope for users to tidy up the entries that they have already created. Currently, tags are generally defined as single words or compound words, which means that information can be lost during that tagging process. Single-word tags lose that information that would generally be encoded in the word order of a phrase.

The commonness of compound tags, including tags that concatenate more than two words, may suggest that users miss the richness of the sentence structure. The “non-breakable space” can be introduces. Although many compound words are produced sing separator characters, such as this_is_tag.

Several del.icio.us taggers have established a private presudo-hierarchy of terms, by establishing tag conventions that resemble directory tructures, such as, Programming/C++, Programming/JAVA.

Smart systems

Alongside education users, there is much that system creators can do to improve the end-data their systems are helping to create. There are tow main ways in which improvements can be made. Firstly, much can be done at the point at which new resources are contributed to the system. Error-checking potentially accounts for a number of tag errors --- although rather fewer misspellings occur than may be expected. Furthermore, some sites already make tag suggestions when users submit resources. Scrumptions, a recent Firefox extension, offers popular tags for every URL. Systems could easily suggest synonyms, expansion of acronyms, and the like when users type in their tags.

Secondly, improvements can be made in the way systems search for resources already in the system. Synonyms suggestions could also be made here, suggesting for example, “ladybug” instead of “ladybird”.

Clay Shirky notes:

“Tagging gets better with scale. With a multiplicity of points of view the question isn’t ‘’ Is everyone tagging any given line ‘correctly’’’, but rather ‘’ Is anyone tagging it the way I do?’’ As long as at least on other person tags something the way you would, you’ll find it – using a thesaurus to force everyone’s tags into tighter synchrony would actually worsen the noise you’ll get with your signal. If there is no shelf, then even imagining that there is one right way to organize things is an error.”

Conclusions

The investigations described in the article are brief, simple and relatively unscientific, as are the number provided within. That the results from both del.icio.us and flickr tended to be rather similar imply that they can be trusted only as much as a short, seat-of-the-pants. Only those with direct access to the del.icio.us nd flickr databases can be aware of the exact state of affairs and how it has changed across the months. For the research purposes, the interesting features of the tags are not in the precise percentages of usage, but in the choice of tag, the choice of structure, and the choice of language. Somewhere around a third of tags were indeed “malformed”, in tat they were beyond the grasp of a multilingual spell-checker for on e reason or another. Many of there were not misspelt, but mis-constructed, some of the latter in a correctable manner.

Still, possibly the real problem with folksonomies in not their chaotic tags but they are trying to serve two masters at once; the personal collection and the collective collection. So it possible to have the best of both worlds? At the moment, many investigations of tag data are in progress, including how tags can be used for searching. As a consequence, development in this fields tends to confine itself to methods for improving the quality of the user-contributed tags for this purpose. In practice, this involves promoting commonly-chosen tags above single-use or infrequently used tags by various means. It is possible that the data collected through folksonomy tagging is more complete than we had imagined. Some single-use tags are explicitly designed as such, such as the latitude/longitude makers used by geotagging. Some may be perceived as valuable or helpful to the reader. Some may be infinitely helpful for search purpose, if only the information provided therein is accessed in an appropriate manner. Is it therefore preferable, rather than attempting to stamp out single use or sloppy tags, to suggest that each item be tagged with mixture of approaches, including several search-friendly keywords?


Source: http://webdoc.sub.gwdg.de/edoc/aw/d-lib/dlib/january06/guy/01guy.html

Folksonomies
Tidying up Tags?

Marieke Guy
UKOLN


Emma Tonkin
UKOLN

from D-Lib Megazine

Draft:The Data Mining of Collaborative Bookmark-sharing System

The Data Mining of Collaborative Bookmark-sharing System

Introduction

Recent year there are online bookmark system on the Internet. User, namely authors, can share their web page bookmark from the centralized portal like Del.icio.us and these webs are categorized by tagging, which means adding keywords to Internet resources without relying on a controlled vocabulary. Therefore information can be indexed and users can access the categorized web page easily base on tags. This process is called the Collaborative Tagging which “describes the process by which many users add metadata in the form of keywords to shared content” (Golder S.A. and Huberman B.A, 2005).

Related Work

Some data mining technique involved in the Collaborative Tagging technology like searching different kinds of web page in the databases, interactive mining based on the user’s preferences, incorporation of background knowledge that integrate the background knowledge in the categorized information in order to find the interestingness of data. “Data mining system can uncover thousands of [interesting] patterns.” (Han J. and Kamber M., 2001). Since the content in the Internet is huge and still growing, it is difficult to conduct the traditional text document control by the traditional data mining method. In addition, the web is “highly dynamic information source … its information is also constantly updated” (Han J. and Kamber M., 2001). Take search engine as an example, data is categorized by the authorized party like the authors or database administrator cannot categorize all the web page from time to time in order to cope with the rapid growing of the web data. Han and Kamber point out that topic of any breadth may contain hundreds of thousand of documents and this can lead to huge number of document entries returned and only small part of documents are relevant. On the other hand, many documents that are high relevant to a topic usually does not contain keywords to defining them. Collaborative Tagging can solve some of the problems since the useful data is categorized by both authors and users in the community. Only useful data are filtered and returned from the system base on the searching relevant tags. Other users can use these categorized and “cleaned” data for searching based on the tags. Sadly, only common tags can return the most relevant web data and usually tag only serve for personal purpose and common tags is hardly implemented.

Tagging can eliminate the word inflections if there is a lemmatization engine, which determines the lemma for a given word, could trigger in the input stage. “Folksonomies (Collaborative Tagging) are characterized by flaws that formal classification systems are designed to eliminate including polysemy and synonyms.“(Wikipedia, 2006). Many data collecting system use tagging to classify the data because people believe that user involvement on the categorization is more accurate and human-readable than the artificial classifier base on the statistics. “Tagging system has the potential to improve search, spam detection, reputation systems and personal organization while introducing new modalities of social communication and opportunities for data mining.”(Marlow C., Naaman M., Boyd D. and Davis M., 2006). However, if certain degree of regulation used in the traditional data mining technique involves in filtering the tagged data can produce more accurate results than simply return all “unclear” tagged information that made by the authors. One of the data mining technique is data cleansing process which can remove the “low-quality, redundant or nonsense metadata, and the potential risks of tidying too nearly and thereby losing very openness that has made folksonomies so popular” (Guy M., Tonkin E., 2006). This project is trying to combine freedom on choosing right tag to categorize the web data and retrieve the useful information by using the data cleansing method in order to create some degree of relationships between the content provider (authors) and the users. Although the tagging system cannot replace for formal system like the search engine but this project can improve the accuracy and relevancy of the returned information and “[treat] this as ring the core quality that makes folksonomy tagging so useful.” (Guy M., Tonkin E., 2006).


References:

Cameron M, M. Naaman, D. Boyd and M. Davis. (2006). HT06, tagging paper, taxonomy, Flickr, academic article, to read. Proceedings of the seventeenth conference on Hypertext and hypermedia. 31-40.

Folksonomy – Wikipedia. [Online]. Wikipedia. Available: http://en.wikipedia.org/Folksonomy [2006, Nov. 8]

Guy M. and T. Emma. (2006, January). Folksonomies: Tidying up Tags?[Online]. D-Lib Magazine 12. Available: http://www.dlib.org/dlib/january06/guy/01guy.html

Jiawei. H., and M. Kamber. (2001) Data Mining: Concepts and Techniques. San Diego, C.A.: Academic Press.

Scott A.G. and B.A. Huberman. (2006). Usage Patterns of Collaborative Tagging Systems. Journal of Information Science,32(2). 198-208

Wednesday, October 18, 2006

HT06, Tagging Paper, Taxonomy, Flickr, Academic article, To read


Tagging System become popular: these system enable users to add keywords (i.e. tags to Internet resources ( e.g., web page, images, videos) without relying on a controlled vocabulary.

Advantage: improve search, spam detection, reputation systems and personal organization while introducing new modalities of social communication and opportunities for data mining.

One approach to tagging has been emerged in “social bookmaking” tools where the act of tagging a resource is similar to categorizing personal bookmarks. In this model, tags allow users to store and collect resources and retrieve them using the tags applied similar keyword-based systems have existed in web browsers, photo repository applications and other collection management systems for many years; however, these tools have recently increased in popularity as elements of social interaction have been introduced, connecting individual bookmaking activities to a rich network of shared tags, resources, and users.

Social tagging systems, as we refer to them, allow users to share their tags for particular resources. In addition, each tag servers as a link to additional resources tagged the same way by others. Because of their lack of predefined taxonomic structure, social tagging systems rely on shared and emergent social structures and behaviors, as well as related conceptual and linguistic structures of the user community. Based on this observation, the popular of tags in social tagging systems have recently been termed folksonomy, a folk taxonomy of important and emerging concepts within the user group.

Another benefits of social tagging system is that a shared pool of tagged resource enhances the metadata for all users, potentially distributing the workload for metadata for all users, potentially distributing the workload for metadata creation amount many contributors. These systems may offer a way to overcome the Vocabulary Problem.

First articulated by George Furnas et al in, where different users use different teams to describe the same things (or actions). This disagreement in vocabulary can lead to missed information or inefficient user interactions. The taxonomy of tagging systems articulated in this paper, and the results of our preliminary experiments on the relationship between tag overlap and social connection, both point to the possibility that thoughtful sociotecnical design of tagging systems may uncover ways o overcome the Vocabulary Problem without requiring either the rigidity and steep learning curve of tightly controlled vocabularies, or the computational complexity and relatively LOW success of purely automatic approaches to term disambiguation.


  1. Resources: the relationship between resources and links is a well-researched area. Most prominently, PageRank [18] has made analysis of link structure on the web a household name.
  2. Users: Analysis of social ties and social networks is an established subfield of sociology [25] and has received attention from physicists, computer scientists, economists and numerous other areas of study.
  3. Tags: The aggregation and semantic aspects of tags have been discussed and debated at length[16]. This discussion has mainly focused on the quality of information produced by tagging systems and the possible tradeoffs between folksonomies and crafted ontologies [17,20]. Furthermore, the challenges of shared vocabularies for description have been studied in the information science and library science communities from many years. [8]

Related work

Perhaps the most significant formal study of tagging systems appears in the work of Golder and Huberman [9]. The authors study the information dynamics in “collaborative tagging systems” – specifically, the Del.icio.us system. The authors discuss the information dynamics in such a system,, including how tags by individual resources( in the case of Del.icio.us, web resources) change – or more specifically, STABLEIZE- over time.

Golder and Huberman also discuss the semantic difficulties of tagging systems. As they point out, polysemy (when single word have multiple related meanings) and synonymy (when different words have the same meaning) in the tag database both hinder and precision and recall of tagging systems. In addition, the different expertise and purposes of tagging participants may result in tags that use various levels of abstraction to describe resources: a photo can be tagged at the “basic level” of abstraction [14] as “cat” of at a superordinate level as “animal” or at various subordinate levels below the basic level as “Persian cat”.

Inherent in our model of tagging systems are connections of links between resources. As mentioned above, research on link-based systems in the context of the web is hardly new. Obviously, the PageRank algorithm had a significant impact on the field and on the way we se the web today, by supplying a mechanism to assess the importance of web pages. Lately, link analysis has been suggested to help fight web spam[10] by identifying trusted resources. In tagging systems, similar concept can utilize the information ad trust in the social network and the links from users to resources (as well as between resources as before) to reason about the importance and trust of users and resources.

Kleinberg [13] suggested an algorithm to identify web pages that are “hubs” and nodes that are “authorities” in a linked graph of resources, given a query term. In his model, Kleinberg views the hubs and authorities approaches an inch closer to our model. Chakrbarti et al [5] extended Kleinberg’s work to include anchor text. Anchor text, the text that appears around a link to a certain resource, can be considered to have a similar role to tag in our model. Traditionally, the anchor text is associated with the resource the link is pointing to. The exact way the text is packed and associated with the resource comprehensiveness and accuracy of anchor-text based methods by treating the user and the resource separately in relevance metrics.

Taxonomy of Tagging Systems

Some key dimensions of tagging system’s design that may have immediate and considerable effect on the content and usefulness of tags generated by the system. For each dimension in our taxonomy, we note that ways in which the location of a system on this dimension may impact the behavior of the system. Some of these dimensions listed below interact; a decision along one of them may determine, or at least be correlated with, the system’s placement in another.

Tagging right: the most important characterization of a tagging system design is the system’s restriction on group tagging. It can restricted to self-tagging, where users only tag the resources they created or allow free-for-all tagging, where any use can tag any resource. This is not the apparent dichotomy that it seems, as systems can allow varying levels of compromise. For instant, system can choose the resources users are to tag or specify different levels of permissions to tag( as with the friends, family, and contact distinctions in Flickr). Likewise, systems can determine who may remove a tag, whether no one or anyone, the tag creator or the resource owner (e.g. Flickr). The implication for the nature of tags that emerge is that free-for-all systems are obviously broad, both in the magnitude of the group of tags assigned to a resource, and in the nature of tags assigned. For instance, tags that are assigned to a photo may be radically divergent depending on whether the tagging is performed by the photographers, their friends, r strangers looking at their photos.

Tagging support. The mechanism of tag entry can have great impact on tagging system behavior. Observed system fall into three distinct categories: blind tagging, where a tagging user cannot view tags assigned to the same resource by other users while tagging (e.g. Del.icio.us); viewable tagging, where the user can see the tags already associated with a resource (Yahoo! Podcasts); and suggestive tagging, where the system suggests possible tags to the user (Yahoo! We 2.0). the suggested tags may be based on existing tags by the SAME user, tags assigned to the same resource by other users. Suggested tags can also be generated from or other sources of related tags such as automatically gathered contextual metadata, or machine-suggested tag synonyms. The implication of suggested tagging may be a quicker convergence to a folksonomy. The suggestive system may help consolidate the tag under resource, or in the system, is much faster than the blind tagging system would. A convergent folksonomy is more likely to be generated when tagging is not blind. On the the hand, the suggestive model may be applied carefully to that the agreement is not too widespread. As for viewable tagging, implications may be overweighting certain tags that were associated with the resource first, even if they would not have arisen otherwise.

Aggregation. Another related feature of group dynamics comes from the aggregation of tags around a given resource. The system may allow for a multiplicity of tags for the same resource which may result in duplicate tags from different users; this approach is named by author as Bag-model (e.g. Del.icio.us). Alternatively, many systems ask the group to collectively tag an individual resource, thus denying any repetition; this interface they called a Set-model approach for tag input(e.g. You Tube, Flickr).

In case of bag-model, he system is afforded the ability to use aggregate statistic for a given resource to present users with the collective opinions of the taggers; for instance, the tags around a popular link on Del.icio.us can be shown to the user to help characterize the breath of opinions of the taggers. Furthermore, these data can be used to more accurately find relationships between users, tags, and resources given the added information of tag frequencies.


User Incentives

Incentives and motivations for users also play a significant role in affecting the tags that emerge from social tagging systems. Users are motivated both by personal needs and sociable interests. The motivations of some users stem from a prescribed purpose, while other users consciously repurpose available systems to meet their own needs or desires, and still others seek to contribute to a collective process.

The most analysis of a tagging system has been completed on data collected from the content bookmaking site Del.icio.us. The reason on choosing Flickr is that Flickr provide an alternative interpretation to the conclusions derived from the study. In nearly every category within the system taxonomy, Flickr occupies an alternate space from Del.icio.us: it contains user-controlled resources as opposed to global; tagging rights are restricted to self-tagging (and at best permission-based, although in practice self-tagging in most prevalent) instead of a free-for-all; tags are aggregated in sets instead of bags; and finally, the interface mostly affords for blind-tagging in stead of suggested-tagging.

These design decisions shape the incentive structures that drive people to tag resources. Since Del.icio.us is largely task-focused namely storing bookmarks for future retrieval, organizational motivations are most dominant. While the social element of tagging is evident from the leveraging of the community contribution, a lack of communication systems (e.g. messaging or explicit social networks) deemphasizes non-organizational social incentives.

Flickr users, on the other hand, are also likely to tag their own retrieval, but coupled with abundance of communication mechanisms, the system design encourages gaming and exploration tag uses. Users are primarily motivated by social incentives, including the opportunities to share and play.

Tag Usage

Tags are not mandatory in the Flickr usage model. Within a social tagging system, tags are typically an optional feature in a larger resource organization task. Like Del.icio.us, the Flickr interface prompts users for metadata bout each resource identified: a title, a caption, and a list of tags. In the case of both systems, the tag input comes third in the input interface, but also differentiates them from other resource management tools.

In addition to tagging one’s own photos, the Flickr system also allows users to tag their friends’ photos. However, this feature is not largely used; of the 58 millions tags they have observed, only a small subset are of this type; an overwhelming majority to tags are applied by the owners of photos.

Tag usage pattern vary quite drastically among Flickr users, and as expected, so does the adoption of tagging behavior. Figure 2 shows the cumulative distribution function (CDF) for tag vocabulary size across the set of users. The value at a given value is the probability (Y-axis) the random user has a set of distinct tags (X-axis) that is larger than collection size. For example, the probability that a Flickr user has more than 750 distinct tags is roughly 0.1%. the distribution illustrates the fact that most users have very few distinct tags while a small group has extremely large sets of tags.


Fig. 3 shows the growth of distinct tags for 10 randomly selected users over the course of uploaded photos. The users were selected as both frequent uploaders (greater than 100 photos) and frequent taggers (greater than 100 tags). Each point on this graph shows the number of distinct tags (Y-axis_ for a given user after the given photo number (X-axis). It is apparent from this plot that a number of different behaviors emerge from this social tagging system. In come cases (such as A in Fig.3 ), new tags are added consistently as photos are uploaded, suggesting a supply of fresh vocabulary and constant incentive for using tags. Sometimes only a few tags are used initially with a sudden growth spurt later on, suggesting that the user either discovered tags or found new incentives for using them, as with users B. for many users, such as those with few distinct tag in he graph, distinct tag growth decline over time, indicating either agreement on the tag vocabulary, or diminishing returns on their usage. Despite the heavy usage of tags for each of the individuals whose tags are depicted in the figure, a number of classes of behavior have arisen; implying that the interaction between user, tag and utility is varies one.

Vocabulary Formation

All tagging systems mentioned in this paper are arguably social in nature; in some cases the social aspect comes from leveraging the community’s collective intelligence, and in others there is explicit social interaction around use of tags.

Conclusions

Social tagging systems have the potential to improve on traditional solutions to many well-studied web and information system problems. Such problem including personalized or biased link analysis, organizing information, identifying synonyms and homonyms, building networks of trust to combat link spam, monitoring trends and drift in information systems and more. The prospects of reasoning about tags, users and resources in unity are encouraging.

Finally, by no means do we contend that the design taxonomy and incentive taxonomy we describe are complete. New uses for tagging systems are invented every day; users of such systems appropriate them with an ever-changing set of goals, motives, and aspirations. We hope that the taxonomy can server as a foundation for researcher and enable a more complete understanding of the constraints and affordances of tag-based information systems.


Tuesday, October 17, 2006

Finished registeration and login page

The pages for registeration and login has been finished.
Next step is re-design the schema in the tables in the DB.
On the other hand, the
store-procedure in the SQL server should be implemented for further development in the later stages.